
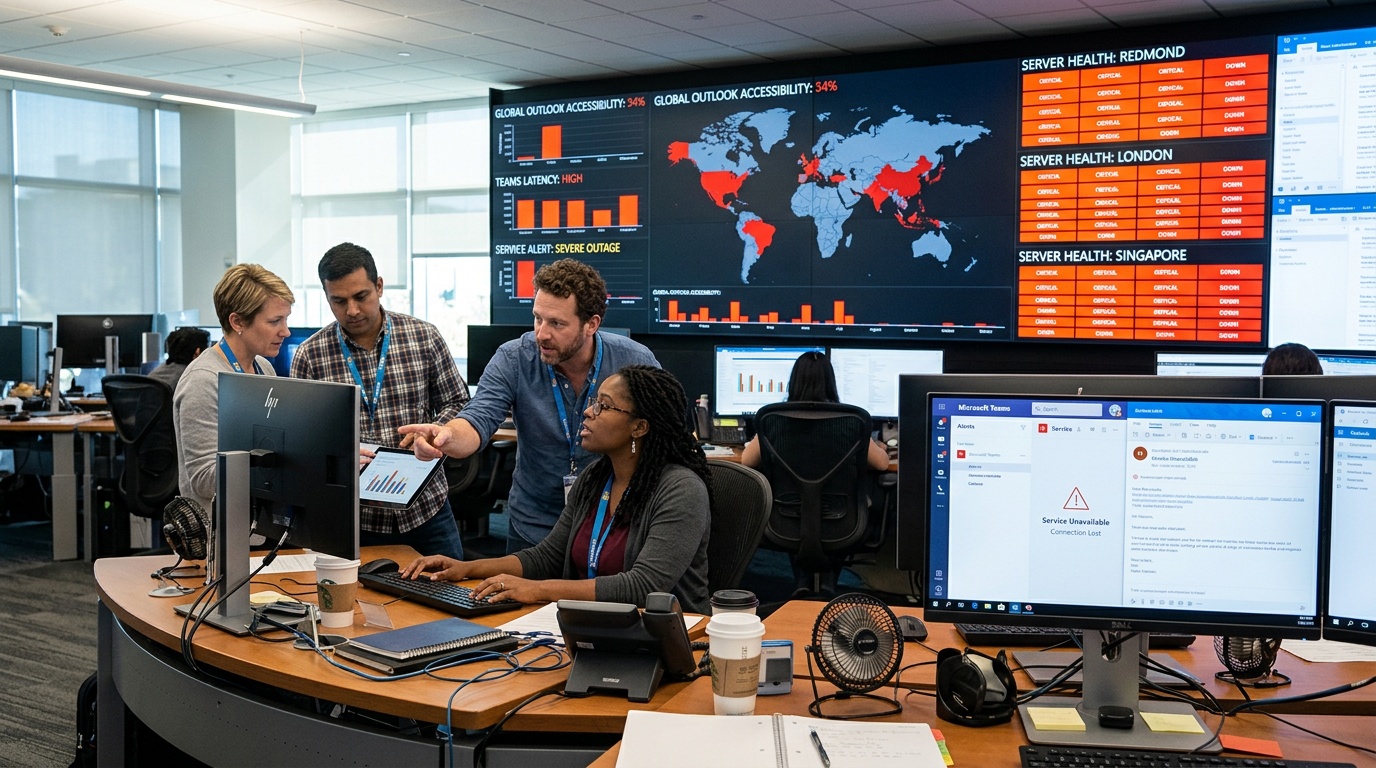
Microsoft moved to restore Outlook, Teams, and other cloud services after a broad global outage disrupted customers. The incident on January 25, 2023, interrupted communication across businesses, schools, governments, and individual accounts. Users reported failed logins, delayed messages, missing calendars, and trouble joining online meetings. Microsoft acknowledged the problem and directed engineers toward its cloud network.
Microsoft used its public status account to confirm that several Microsoft 365 services faced connectivity failures. It also posted updates through service-health tools available to administrators. Those notices gave customers a shared source while local support teams handled complaints. The early messages did not promise an immediate recovery time. Instead, Microsoft said its teams were tracing the fault and testing corrective actions.
A global disruption reaches Microsoft customers
The outage affected customers across Europe, Asia, Africa, the Middle East, and the Americas. Its reach reflected Microsoft’s extensive cloud network and large international customer base. However, the incident did not affect every customer equally. Some people retained partial access, while others could not reach essential services. That uneven experience made the outage difficult for organizations to assess quickly.
Microsoft identified problems involving Microsoft Teams, Exchange Online, Outlook, SharePoint Online, and OneDrive for Business. Customers also reported trouble with Microsoft Graph, Power BI, and the Microsoft 365 administration center. Some Azure users experienced connectivity problems involving cloud resources and management features. These overlapping failures pointed toward shared infrastructure rather than separate application faults.
Public reports reveal the outage’s scale
Outage-tracking websites recorded sharp increases in complaints as employees began their working days. Users described problems through social networks, company support channels, and community forums. Downdetector gathered thousands of reports from several countries during the disruption. However, those reports represented voluntary complaints rather than a complete customer count. Microsoft’s internal telemetry provided a broader view of service health.
Teams and Outlook failures disrupt daily work
Teams users encountered delayed messages, failed calls, and difficulties joining scheduled meetings. Some customers could open the application but could not load recent conversations. Others experienced missing features or repeated connection warnings. These failures disrupted organizations that used Teams for meetings, project coordination, and customer support. The outage therefore affected more than ordinary workplace messaging.
Outlook and Exchange Online customers also faced serious interruptions. Some users could not open their mailboxes, while others struggled to send or receive messages. Calendar access became unreliable for certain customers, complicating meeting schedules and appointments. Desktop users sometimes retained locally cached messages, but server-based actions still required working connections. Consequently, partial access did not provide a complete solution.
Microsoft traces the failure to a network change
Microsoft eventually linked the incident to a change within its wide-area network. That network connects data centers, cloud regions, customers, and internet providers. A planned configuration update changed addressing information on network routers. The change triggered packet-forwarding problems and interrupted communication between important systems. Applications then struggled because they could not reliably reach dependent services.
Microsoft’s automated safeguards stopped the network update after detecting trouble. However, those controls could not immediately reverse every change already applied. Engineers needed to roll back the faulty configuration across a large and complex environment. That process required careful coordination because rushed changes could create additional instability. The diagnosis gave restoration teams a clear path forward.
Microsoft attributed the outage to the configuration problem rather than a cyberattack. The company disclosed no evidence connecting the incident with malicious activity. It also described availability failures instead of reporting lost customer data. That distinction mattered because service interruptions and security breaches require different responses. Administrators still monitored their systems while Microsoft completed its technical investigation.
Engineers begin a controlled restoration
Microsoft’s engineers rolled back the network change and watched for improving connectivity. The company also connected services with additional infrastructure to support recovery. These actions gradually restored links between Microsoft 365 applications and their supporting systems. Engineers reviewed service telemetry throughout the process. That evidence helped them confirm whether each corrective step produced the intended result.
Recovery arrived in stages rather than through one immediate switch. Some regions regained access before others because traffic patterns and network routes differed. Individual applications also recovered at different speeds. Teams messaging could improve while calendars or meeting features still showed problems. Microsoft therefore continued monitoring after its first signs of recovery appeared.
Verification continues after access returns
Restoring access marked only one part of the response. Microsoft needed to verify that systems remained stable under normal traffic. Engineers examined error rates, connection success, message delivery, and application performance. They also checked dependencies connecting identity systems, storage services, and customer applications. This validation reduced the risk of declaring recovery before every major component stabilized.
Status updates guide administrators
Microsoft communicated through its Microsoft 365 Status account and administrator service-health dashboards. Public updates summarized the investigation, rollback, and recovery without exposing sensitive network details. Administrators received more specific notices through protected customer portals. Those messages helped technology teams distinguish Microsoft’s outage from local network problems. Clear identification prevented some organizations from making unnecessary internal changes.
However, customers still wanted faster estimates and more detailed explanations. Large organizations often plan around stated recovery times during major incidents. Microsoft avoided firm deadlines while engineers evaluated changing conditions. That approach limited inaccurate promises but left customers uncertain. The tension shows why outage communication remains a critical part of cloud operations.
Organizations confront operational consequences
The disruption demonstrated how deeply organizations depend on Microsoft’s cloud services. Employees use Outlook for correspondence, calendars, approvals, and automated notifications. Teams supports meetings, calls, shared documents, and internal conversations. When both platforms fail together, organizations lose several communication channels simultaneously. Customer service, remote work, education, and routine administration can quickly slow down.
Many businesses turned to telephone calls, personal messaging platforms, or competing meeting tools. These alternatives supported urgent work but created governance and security concerns. Regulated organizations must protect sensitive information even during an outage. Employees also needed clear instructions about approved backup channels. The incident therefore tested business continuity plans alongside Microsoft’s technical recovery.
The outage highlights shared cloud dependencies
Cloud platforms distribute applications across many facilities, but shared networks still connect those components. A single configuration problem can therefore affect several otherwise separate products. Redundant servers cannot help when traffic cannot reach them reliably. Providers must combine redundancy with controlled changes, automatic safeguards, and tested rollback procedures. Microsoft’s response illustrated both the strengths and limitations of that model.
Customers can also reduce risk through independent communication channels and documented outage procedures. Administrators should know where Microsoft publishes verified service information. Organizations can maintain alternative meeting options for essential operations. They can also identify activities that require immediate access to email or cloud files. These preparations cannot prevent outages, but they can limit operational disruption.
Service recovery leads to further review
Microsoft later reported that the affected services had recovered after engineers restored network connectivity. The company continued reviewing the event and its change-management controls. Major providers routinely use such reviews to identify technical and procedural improvements. For customers, the outage offered a practical reminder about concentrated cloud dependence. Outlook and Teams returned, but resilience remained a shared responsibility.
